Reasoning models generate hidden tokens before they answer, and the API reports them in usage.completion_tokens_details.reasoning_tokens. It is easy to assume that number is always part of completion_tokens. Through Microsoft Foundry’s Model Router, which sends one Chat Completions request to whichever model it chooses, it depended on the model.
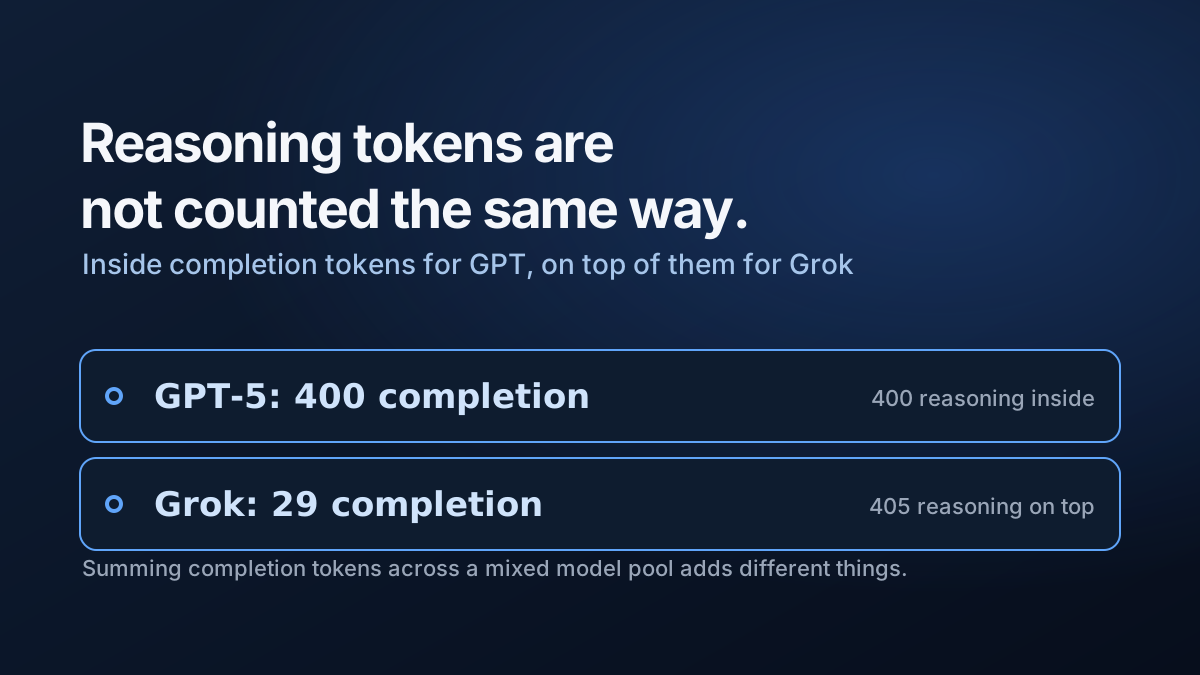
A GPT-5 response:
completion_tokens:   400
reasoning_tokens:    400     (inside the 400)
A Grok 4.1 Fast Reasoning response, asked which is larger, 9.11 or 9.9:
completion_tokens:   29
reasoning_tokens:    405     (more than the completion total)
Reasoning can only be larger than the completion count if it is not part of it. Grok reported its reasoning on top. Across sixteen Grok responses, completion tokens totalled 1,219 and reasoning tokens 3,754.
So a dashboard that sums completion_tokens across a mixed pool of models is adding two different things. For the GPT responses it includes the hidden thinking; for Grok it leaves most of it out.
I have not compared either to an invoice, so I can’t say which number each provider bills. But for counting, the safe approach is to record both fields, per model, and never treat “completion tokens” as comparable across providers without checking which way each one reports.